
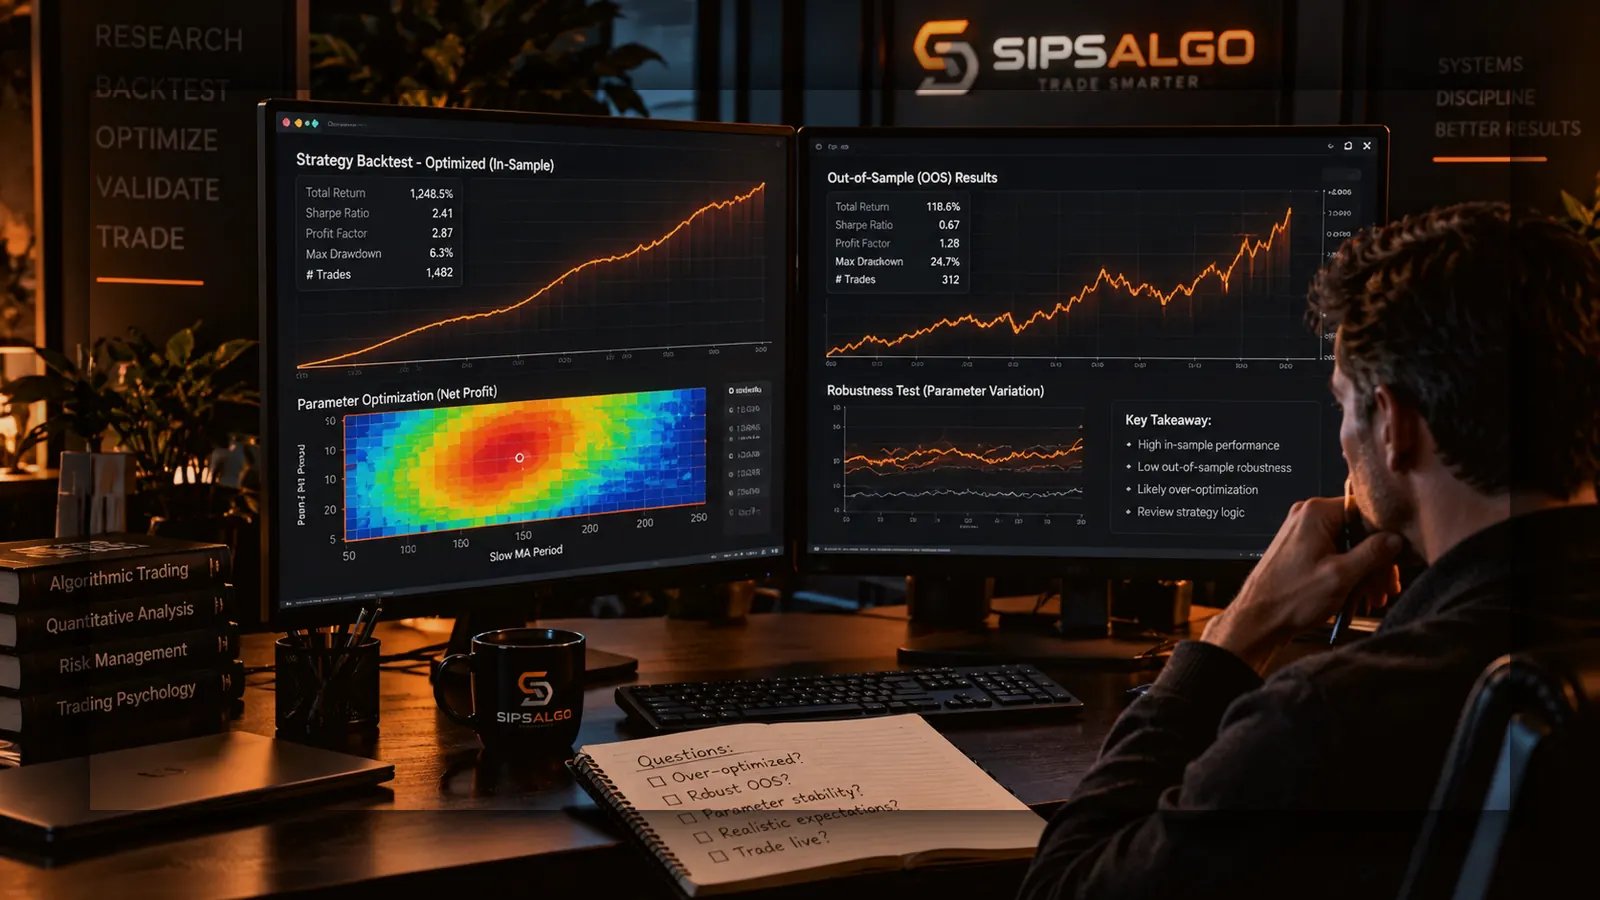
There is a specific, counter-intuitive trap in systematic strategy design: the harder you optimise a strategy against a fixed set of historical data, the better its backtest tends to look — and past a certain point, the worse the strategy tends to become. This is over-optimisation, or curve fitting, and it is one of the more important ideas to understand before trusting any backtest that looks unusually good.
What curve fitting actually is
Any rule-based strategy has parameters — entry thresholds, stop distances, filters, and so on. Testing many combinations of these parameters against the same historical data and keeping whichever combination produced the best result is a natural, almost irresistible process. The problem is that historical price data contains both genuine, persistent patterns and pure noise — random fluctuation that happened to occur in that specific window and won’t repeat the same way again. Enough optimisation against enough parameters will eventually find a combination that fits the noise as well as (or better than) it fits any genuine pattern, simply because there are so many possible combinations to search through.
The resulting strategy isn’t dishonest — nothing about the process involved lying about the data. It has simply been shaped, in part, to match specific historical accidents that have no reason to repeat.
Why complexity makes this worse
The more free parameters and conditional rules a strategy has, the more ways it has to fit noise rather than signal. A simple strategy with two or three parameters has relatively few ways to overfit; a strategy with a dozen interacting filters and thresholds has vastly more. This doesn’t mean complexity is always bad — some genuine patterns are complex — but added complexity should come with added scrutiny, not just added confidence because the backtest improved.
The out-of-sample idea
One of the standard defences against curve fitting is holding back a portion of historical data — an out-of-sample period — that is never used during strategy design or optimisation, and only checked afterward. A strategy that performs reasonably on data it was never tuned against is giving real evidence that its logic has some generality, rather than being purely fitted to the specific window it was built on. A strategy that performs well in-sample but falls apart out-of-sample is a strong warning sign, regardless of how impressive the in-sample number looked.
Restraint is a design choice, not a limitation
There is a natural pull toward optimising further whenever a small tweak seems to improve the backtest. Resisting that pull — accepting a slightly lower in-sample result in exchange for simpler logic and fewer tuned parameters — is a deliberate trade-off, and often the right one. A strategy that looks merely good rather than spectacular, and holds up reasonably out-of-sample, tends to be a more trustworthy foundation than one that looks spectacular in-sample and has never been tested against data it wasn’t shaped by.
Why the highest historical return can be deceptive
Sorting a strategy library by historical return and trusting the top result is, in effect, sorting partly by how much curve fitting each strategy happened to accumulate — because curve fitting, when it occurs, tends to push the in-sample number up. The strategy at the very top of that sort is not necessarily the best strategy; it may simply be the one whose fitting to historical noise went furthest. This is one of the reasons robustness checks, out-of-sample evidence, and parameter stability deserve at least as much attention as the headline backtest figure — see Why a Great Backtest Does Not Automatically Mean a Great Trading Strategy.
What to watch for, without a universal threshold
There is no single numerical rule that reliably separates a well-fitted strategy from a genuinely curve-fitted one — this article deliberately avoids suggesting one, because a threshold that sounds authoritative but isn’t actually supported by evidence is worse than no threshold at all. What’s useful instead is a set of warning signs worth weighing together: unusually high complexity relative to the strategy’s logic, a large gap between in-sample and out-of-sample performance, and results that change dramatically with small parameter adjustments.
Where this fits in the SIPS workflow
Strategy Performance shows a strategy’s FULL/IS/OOS split where genuinely available, so an out-of-sample comparison is possible directly from the data rather than assumed. Monte Carlo Testing Explained covers a complementary way of exploring whether a result depends too heavily on the exact historical sequence it was tested against.
The practical takeaway
A backtest that improves every time you tune it a little further is not necessarily getting more accurate — past a point, it may just be getting better at describing history that already happened. Restraint, out-of-sample evidence, and healthy scepticism toward an unusually strong result are the practical defences, since no single number can reliably substitute for them.